Latham & Watkins is buying Nvidia hardware and fine-tuning open-weight models on infrastructure only its own people can touch. That is not a startup experiment. It is the second-largest U.S. law firm, with $8.3 billion in 2025 revenue, treating AI as something it can own rather than rent.
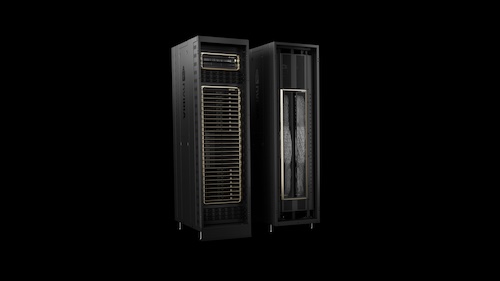
The firm has spent about three years assembling Nvidia GPU servers—multiple H200 systems so far, with Blackwell and Vera Rubin on the shopping list—and housing them in a locked third-party data center that only Latham employees can access. Its machine-learning and software engineers are fine-tuning Nvidia’s Nemotron 3 open-weight models for the firm’s own work. It is the first major law firm to go public with this kind of in-house stack.
The logic is straightforward. A firm like Latham sits on decades of contracts, negotiations, client files, deal context, and institutional legal reasoning. Sending the most sensitive of that material to a frontier lab’s API means paying expensive tokens and accepting the residual risk that the data lives on someone else’s systems. CIO Rene Mendoza put it plainly: some client information is sensitive enough that the firm does not want it with “any cloud vendor.” The on-prem setup also lets Latham stitch models into its own software instead of living inside a vendor’s product. Michael Rubin, who chairs the firm’s AI strategy committee, said that combination “puts us in a class that other law firms can’t match.”
This is not a full divorce from OpenAI, Anthropic, or legal-AI products like Harvey. Latham is running a hybrid stack: commercial tools for a lot of work, private compute and open weights for the work it does not want to export. Token cost is a factor. Control, security, and optionality are the bigger ones. The firm is not hitching its wagon to one company.
That is the part that traveled so far on X. Anand Iyer framed it as the enterprise sovereign AI stack: open weights + proprietary data + local compute. Ayush’s follow-up made the sharper claim: the largest customers do not have to stay forever on frontier APIs. They can own the hardware, keep the data, fine-tune around the workflow, and switch when price or quality moves.
The tweet overreaches when it treats this as proof that the labs have “no moat” and that regulation is only a cartel play. Frontier models still matter for hard reasoning, messy edge cases, and work where a mistake is expensive. Latham is not training a foundation model from scratch. It is customizing open weights for a high-volume, high-confidentiality professional service business. That is still a different product from GPT- or Claude-class systems. But the strategic point stands: for a large share of enterprise AI work—summarizing, classifying, drafting, retrieving, repeating the same patterns thousands of times—the customer does not need the most expensive model on the most expensive meter. It needs a good-enough model on data it controls, running inside a workflow it owns.
What this means for large firms going forward
Large firms with money, sensitive data, and repeatable work are going to stop treating AI as a single vendor relationship and start treating it as a stack they assemble. The pattern is already visible: keep frontier APIs for the hard problems, stand up private clusters for the confidential and high-volume work, fine-tune open weights on institutional knowledge, and refuse to let one lab become the only door in or out. Law is an early, loud example because privilege and client confidentiality make the data-leakage problem existential. Banks, insurers, hospitals, defense contractors, accountants, and any company sitting on a multi-decade corpus of proprietary process will face the same calculus.
That does not mean every firm should buy a room of H200s tomorrow. Hardware, security, ML talent, and model operations are expensive and easy to do badly. Latham can afford a 900-person tech organization with roughly 100 people on AI. Most companies cannot. The real fork is not “cloud versus on-prem.” It is who owns the loop: data, workflow, evaluation, and the right to swap models when a cheaper or better open-weight system appears.
Going forward, the winners among large firms will be the ones that treat models as interchangeable components and treat their own data and process as the scarce asset. The losers will be the ones that lock their most valuable knowledge into a single API, then discover the price, the terms, or the risk profile changed after the knowledge was already gone. Latham is not ending the frontier labs. It is showing what happens when a sophisticated buyer decides the model is not the business—the business is.